Models
What is Nano Banana? Editing photos with Google's image model
Nano Banana is the nickname of Google's Gemini image models. You upload a photo, say in one sentence what should change, and the model keeps the rest. This guide covers the versions, prompt examples and limits.
Zling AI Team10 min read
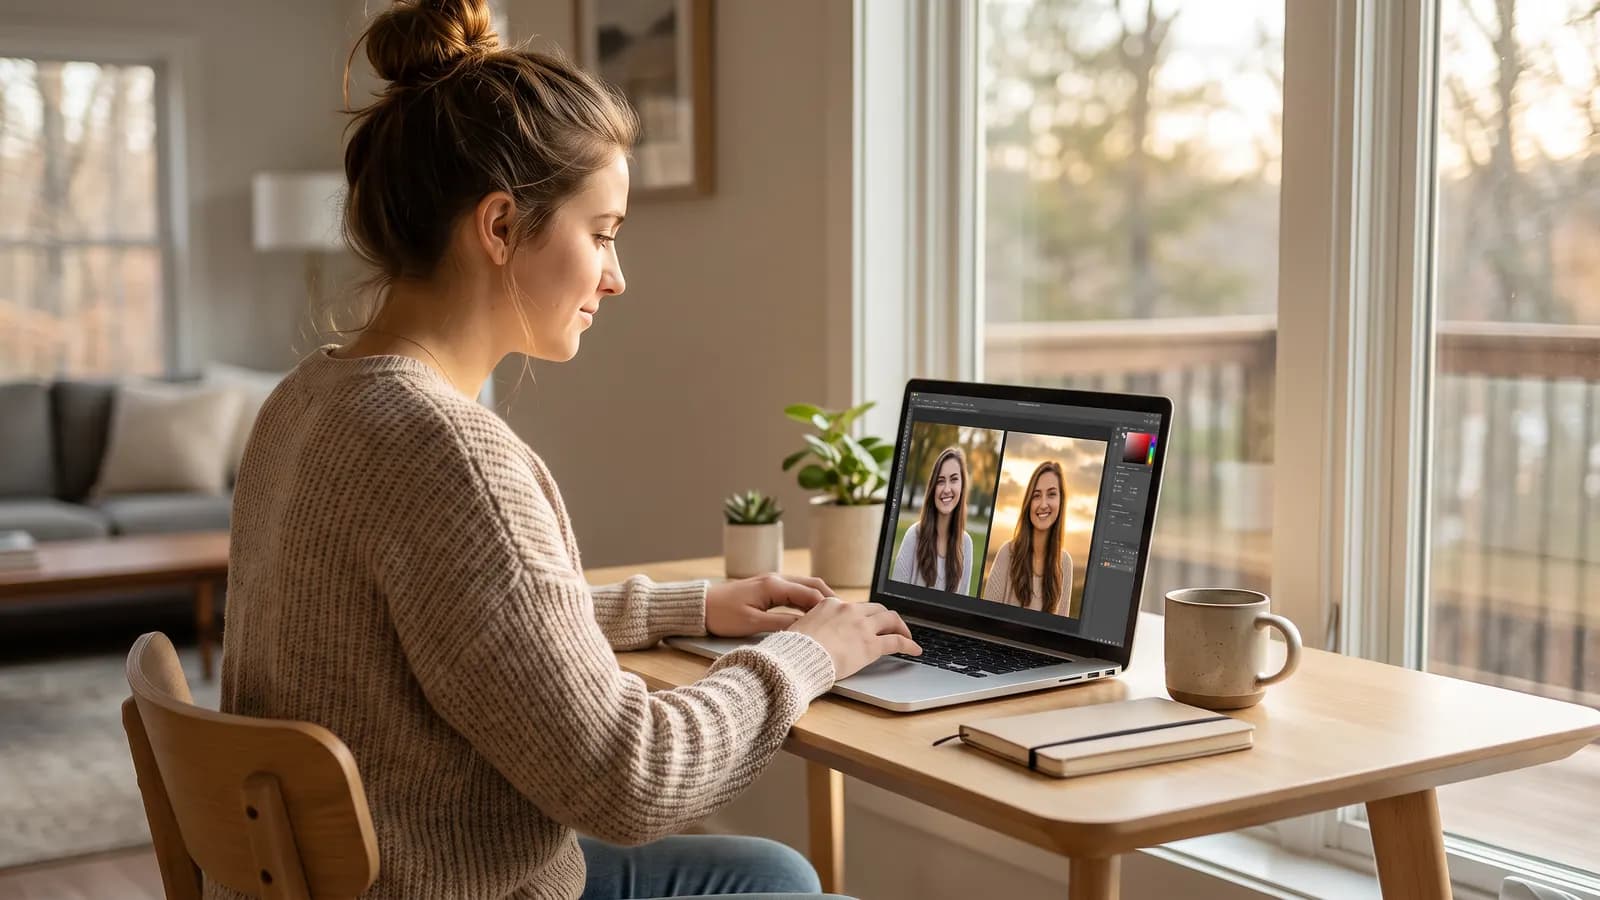
The short answer: Nano Banana is the nickname of Google's Gemini image models. The first version came out in August 2025 as Gemini 2.5 Flash Image, followed by Nano Banana Pro and Nano Banana 2. You upload a photo and write in a plain sentence what you want changed, and the model makes the edit while trying to keep the rest of the image intact. This guide covers the family members, what they can do, how to write prompts for them and the limits Google lists in its own documentation.
What is Nano Banana, and which Gemini model is it?
Nano Banana is not a single model but the name of a model family. Google uses the name in its official announcements too, and maps every version to a Gemini model. As of October 2026, when this guide was written, the family in Google's developer documentation and announcements looks like this:
| Name | Gemini model | Announced | Highlights |
|---|---|---|---|
| Nano Banana | Gemini 2.5 Flash Image | August 2025 | Natural-language editing, image blending, character consistency |
| Nano Banana Pro | Gemini 3 Pro Image | November 2025 | Legible multilingual text, up to 14 input images, 2K and 4K output |
| Nano Banana 2 | Gemini 3.1 Flash Image | February 2026 | Strong world knowledge at Flash speed, output from 512 pixels to 4K |
| Nano Banana 2 Lite | Gemini 3.1 Flash Lite Image | June 2026 | The fastest and most cost-efficient member of the family |
| Nano Banana 2.1 | Based on Gemini 3.6 Flash | October 2026 | An update to Nano Banana 2; better prompt adherence and text |
Which one you use depends on where you use it. According to Google's announcements, these models are offered in the Gemini app, in AI Mode in Google Search, in Google AI Studio and the Gemini API for developers, and through Google Cloud for businesses. Apps change their default model from time to time: when Nano Banana 2 launched, it replaced Nano Banana Pro in the Gemini app, while Pro stayed available to Google AI Pro and Ultra subscribers through a menu. Checking your tool's settings to see which version it runs is a good habit.
What can Nano Banana do?
What sets it apart from classic text-to-image models is that editing sits at the centre. The model both creates images from scratch and changes an image you upload based on a written instruction. The capabilities Google highlights in its announcements are these:
Editing in natural language
You upload a photo and write a sentence such as “blur the background” or “remove the stain on the T-shirt”; there is no mask to draw and no layers to manage. Google's announcement of the first version gives exactly this kind of targeted edit as an example. According to the Gemini API documentation, when you add an element to an image, the model tries to match it to the original image's style, lighting and perspective.
Blending several images
You can combine several images into a single composition: placing a product in a new scene, reupholstering a room with another fabric, or bringing together elements from two photos. The documentation gives different recommendations per version: the first Nano Banana works best with up to three input images, while Nano Banana Pro can handle five images with high fidelity and up to 14 images in total.
Character consistency
Keeping the same person, mascot or product looking similar across scenes matters for stories, catalogues and social media series. Google says Nano Banana Pro can maintain the consistency and resemblance of up to five people. The documentation's advice is practical too: when generating the same character from different angles, include the images you generated earlier in your next prompts. Still, the Nano Banana 2.1 model card states plainly that character consistency between input and output is not perfect.
Text in images and translation
Legible, multilingual text inside images came to the fore with Nano Banana Pro. Nano Banana 2 can also translate and localise the text in an image into another language. That is useful for menus, posters, cards and presentation visuals. The documentation's tip: generate the text first, then ask for an image with that text, for better results.
World knowledge and search grounding
The model draws on Gemini's general knowledge. Nano Banana Pro and some later versions can generate images based on current information from Google Search, such as the weather or a match result. This helps with infographics and diagrams, but not every version has it: according to the documentation, Nano Banana 2 Lite does not support search grounding.
How do you edit a photo with Nano Banana? Step by step
- Pick the right photo: choose a sharp, well-lit shot in which the area you want to edit is clearly visible. If other people are in the photo, think about their consent.
- Start with a single change: write one clear request, such as “turn the background into a beach in late-afternoon light”.
- Say what should stay: add a sentence such as “keep the face, hair and outfit exactly as they are”. The editing templates in the documentation also explicitly ask for the rest of the image's style, lighting and composition to be preserved.
- Continue in conversation: if you don't like a detail, don't start over; write a follow-up such as “make the lighting a bit warmer” or “keep everything the same, but make the expression more serious”.
- Set the ratio and resolution: if your tool allows it, choose the aspect ratio and size (such as 1K, 2K or 4K). A small size is enough for drafts; take the final version at a large size.
- Check and label: review text, hands and directions. When sharing, saying that the image was edited with AI is a good habit.
Prompt examples for photo editing
The examples below follow the structure recommended in Google's documentation: say what changes, how it should look and what should be preserved, all in the same prompt.
Changing the background:
Replace the office wall behind the person in this photo with a calm beach scene in late-afternoon light. Keep the person's face, hair, outfit and posture exactly the same; make the direction of the light match the new background.
Removing an object:
Remove the red mug from the table and fill the empty space with the table's wood texture. Keep the rest of the image, its lighting and its composition exactly the same.
Restoring an old photo:
Clean up the scratches and dust on this old family photo, then colourise it with natural, understated colours. Do not change the facial features or the patterns of the clothes.
Combining two images:
Place the ceramic vase from the first image on the sunny kitchen counter from the second image. Keep the vase's colour and texture; its shadow should match the light coming through the window. Square format.
Text in the image:
Design a simple birthday card in pastel tones. In the centre, elegant handwritten-style lettering reads “Happy birthday, Deniz”, surrounded by small wildflowers.
A scene built step by step:
First, create a background of a pine forest on a misty morning. Then add an old, moss-covered stone bridge in the foreground. Finally, place a hiker in a red coat on the bridge, seen from behind.
Which prompting techniques does Google recommend?
The “best practices” section of the Gemini API documentation lists six habits for good results:
- Be very specific: instead of “fantasy armour”, describe its material, pattern and shape. The more detail you give, the more control you have.
- Explain the purpose: saying “create a logo for a high-end, minimalist skincare brand” instead of “create a logo” helps the model understand the context.
- Iterate: don't expect a perfect result on the first try; ask for small corrections within the conversation.
- Break complex scenes into steps: background first, then foreground, then the details.
- Describe what you don't want in positive terms: write “an empty, deserted street with no signs of traffic” instead of “no cars”. The documentation calls these semantic negative prompts.
- Direct the camera: set the composition with photographic terms such as wide-angle shot, macro shot or low-angle perspective.
The documentation's general advice is to describe the scene in rich detail, in flowing sentences. Two or three sentences that answer “who, where, doing what, with light coming from where” make better use of the model's language understanding than a list of disconnected keywords.
Can I write prompts in Turkish or other languages?
You can, but there is a detail worth knowing. For best performance, the Gemini API documentation lists these languages: English, Arabic, German, Spanish, French, Hindi, Indonesian, Italian, Japanese, Korean, Portuguese, Russian, Ukrainian, Vietnamese and Chinese. Turkish is not on that list. That doesn't mean Turkish prompts won't work, but results may be less predictable. For important work, writing the prompt in English and giving any Turkish text you want in the image verbatim in quotation marks is a safe approach. Always check that special characters such as ğ, ş, ı and İ come out correctly.
What are Nano Banana's limits?
Google's documentation and the Nano Banana 2.1 model card list the limits openly:
- Small and long text: according to the model card, small text, long paragraphs and multi-page text are still weak spots.
- Consistency and pose: character consistency is not always fully achieved, and occasionally the pose of the input image stays unchanged.
- Left-right confusion: the model sometimes mixes up left and right; check results for requests that involve direction.
- Factual accuracy: world knowledge, 3D reasoning and factuality are limited; always verify the figures in infographics.
- Editing with masks and doodles: the model card notes that instructions may be followed only partially in mask- or doodle-based edits.
- Number of outputs: according to the documentation, the model won't always follow the exact number of images you ask for.
- Real people and search: according to the documentation, search grounding in Nano Banana 2 and 2.1 does not use real-world images of people from web search.
There is also responsibility on your side: getting consent before editing someone else's photo and not depicting real people in a misleading way is the right thing to do, whatever the tool.
SynthID: how can you tell an image was made with AI?
Google adds an invisible SynthID digital watermark to images created or edited with Nano Banana; the Gemini API documentation also states that every generated image carries it. The watermark can't be seen with the eye, but Google's tools can detect it.
With Nano Banana Pro, a verification feature arrived in the Gemini app: you can upload an image and ask whether it was generated with Google AI. The Nano Banana 2 announcement added that SynthID is paired with interoperable C2PA Content Credentials. According to the Nano Banana Pro announcement, images from free and Google AI Pro users also carry a visible Gemini mark.
Common mistakes
- Not saying what should stay: if you only write the change, the model may also change the face, the light or the framing.
- Asking for everything in one prompt: instead of requesting five changes at once, work through them one by one in the conversation.
- Writing “no …”: describe what you want to see instead of what you don't want.
- Packing long text into the image: keep the text in the image short and give the exact wording in quotation marks.
- Sharing without checking: in images with infographics, maps or dates, check the figures and the spelling.
- Not saying where the image will be used: mentioning the destination (vertical story, print, slides) makes choosing the ratio and style easier.
Summary
- Nano Banana is the nickname of Google's Gemini image models; there are Nano Banana, Pro, 2, 2 Lite and 2.1 versions.
- Its main strength is editing with words: ask for the change in one sentence and state clearly what should stay.
- It can blend several images, tries to keep characters consistent across scenes and can render legible text in images.
- Turkish is not on the documentation's best-performance list; English prompts are more predictable for important work.
- Small text, left-right direction and factual accuracy still need checking.
- Outputs carry a SynthID watermark, and you can verify images in the Gemini app.
Frequently asked questions
What is the difference between Nano Banana and Nano Banana Pro?
Nano Banana (Gemini 2.5 Flash Image) is the first and fast member of the family. Nano Banana Pro (Gemini 3 Pro Image) was designed for more complex work: legible multilingual text, up to 14 input images, consistency for up to five people, and 2K and 4K output. Google positions the later Nano Banana 2 for fast generation and Pro for work that needs maximum factual accuracy.
Is Nano Banana free?
The Gemini app gives free users a limited quota; according to the Nano Banana Pro announcement, free users who reach it revert to the original Nano Banana model. For developers, Gemini API usage is billed by model and resolution; check Google's pages for the current terms.
How can I tell an image was made with Nano Banana?
Google adds an invisible SynthID watermark to images created or edited with these models. You can upload the image to the Gemini app and ask whether it was generated with Google AI. With Nano Banana 2, SynthID was also paired with C2PA Content Credentials.
Will it work if I write my prompt in Turkish?
It can, but Turkish is not among the languages the Gemini API documentation lists for best performance. For important work, writing the prompt in English and giving the Turkish text for the image verbatim in quotation marks gives more predictable results; still check the Turkish characters.
How many photos can I combine at once?
It depends on the version. According to the documentation, the first Nano Banana works best with up to three input images, while Nano Banana Pro can handle five images with high fidelity and up to 14 in total. Starting with fewer images and stating each one's role clearly in the prompt improves the result.
Sources
- Google Developers Blog (2025), Introducing Gemini 2.5 Flash Image
- Google (2025), Nano Banana Pro: Gemini 3 Pro Image
- Google (2026), Nano Banana 2: Google's latest AI image generation model
- Google (2026), Start building with Nano Banana 2 Lite and Gemini Omni Flash
- Google DeepMind (2026), Nano Banana 2.1 model card
- Google AI for Developers: Image generation with Gemini (Nano Banana)
Related posts
Models
Video generation with Veo 3.1: what it does and where it stops
Veo 3.1 is Google DeepMind's model that turns text and photos into short videos with sound. We cover what it can do according to the official docs, its length and resolution limits, and how to build a good video prompt.
9 min read
Models
From photo to video with Kling: motion, camera and length
Kling is Kuaishou's video model: it takes a photo as the starting point and animates it according to the motion you describe. We cover lengths by version, camera and motion prompts, video with sound and common mistakes.
9 min read
Models
Seedance and Seedream: ByteDance's video and image models
Seedance makes video and Seedream makes images; both come from ByteDance's Seed team. We cover the versions, the capabilities in the official announcements, which one to pick for which job and how to use both in one workflow.
8 min read